AI regulation explained simply: pick the harm that matters to you first, whether biased decisions, fake media or unfair workplaces, then look at the rule or standard aimed at it. Proposals converge on trustworthy output, managed bias and disclosure.
Readers who need a jurisdiction rather than a theme can go straight to How The U.S. Is Regulating AI In 2026: What Businesses And Citizens Need To Know – Technopolicy, China’s AI Regulation 2026: What Companies Need To Know Now – Technopolicy or Canada’s AI Rulebook 2026: What New Regulations Mean For Businesses, Developers, And Citizens – Technopolicy. This page does something different. It follows the rules down to what they change for jobs, information and fairness.
Choosing where to start
The most useful first decision is not which law to read but which everyday effect you are trying to understand. AI rules are written in abstract terms such as trustworthiness, accountability and risk. People feel them as a rejected application, a convincing fake voice message or a search answer with no label. Starting from the effect tells you which part of the rulebook is relevant and which can wait.
- You are on the receiving end of automated decisions. Start with the fairness and bias section below. It explains what harmful bias is, why it appears and what a standards body means by managing it.
- You publish, share or rely on online media. Start with the deepfakes and information section. It covers the risks of synthetic voices and images and the proposal that AI search tools disclose their use.
- You build, buy or deploy generative AI. Start with the section on how governments approach generative AI. It covers training data, self-certification, forbidden uses and audits.
- You manage people, teach or hire. Start with the section on work, learning and sector rules. Tools used in those settings are the clearest case for rules that differ by sector.
- You want to know how problems get surfaced. Start with the section on standards, certification and reporting.
Three criteria help you judge any AI rule you meet. First, does it name the harm it is preventing, or only the technology? Second, does it say who is accountable, such as the supplier, the deployer or a regulator? Third, does it say how compliance is checked, whether by the supplier’s own declaration or by outside audit? A rule that answers all three is usually easier to follow and easier to enforce than one that states values alone.
What AI regulation is trying to achieve
AI regulation aims, at its core, to make AI output trustworthy and to protect people from harm when they use AI-assisted products. That is the first of the proposed principles in a set of principles for AI regulation from Prometheus Endeavour, dated 29 June 2023: AI-related legislation must ensure that AI output is trustworthy and protects human users of AI-assisted products and systems from harm. These are proposals from a policy group, not enacted law. They are still a useful map, because they put into plain language ideas that appear across many national approaches.
The word trustworthy needs a definition to be actionable. NIST, the United States standards body behind the NIST AI Risk Management Framework, defines trustworthy AI through a list of characteristics. As quoted in the Prometheus Endeavour article, they include being valid and reliable, safe, secure and resilient, and accountable and transparent. NIST also says trustworthy systems should be fair with their harmful bias managed. Two features of that list matter for readers.
- It is a set of qualities, not a single test. A system can be accurate in lab conditions yet opaque or unfair in use, so trust has to be judged on several fronts at once.
- It says managed, not eliminated. Bias is treated as something to identify and control, which sets a realistic expectation for what compliance can deliver.
A standards-based approach suits organisations that want to show good practice before any binding rule applies. A legislative approach is better where harm is serious enough that voluntary practice cannot be relied on. In practice the two work together. Standards supply the vocabulary, and law decides which parts become mandatory and for whom.
Fairness and algorithmic bias
Algorithmic bias affects people by repeating, at scale, patterns that were present in the data a system learned from. A technology commentary on AI regulation and self-regulation makes the core point plainly: AI can perpetuate biases present in its training data. If past decisions in hiring, lending or policing reflect unequal treatment, a system trained on those records can treat similar people unequally in the future, and do so consistently.
How AI bias reaches ordinary decisions
The effect is easiest to see where a score or ranking sits between a person and an opportunity. A candidate whose application is filtered before any human reads it has no chance to explain. A resident whose neighbourhood is flagged by a prediction tool may experience more scrutiny without knowing why. In both cases the harm comes from the combination of historical data, an automated step and a lack of visibility. It does not require anyone to intend discrimination. This is why fairness appears in NIST’s list of trustworthy characteristics rather than being left to general ethics.
For concrete cases, Algorithmic Bias Examples: 7 Real-World Cases That Reveal Hidden Harms (2026 Guide) – Technopolicy walks through documented incidents. Readers interested in the criminal justice setting, where a score can influence liberty, can follow predictive policing explained.
What managing bias implies in practice
If the standard is harmful bias managed, three practical expectations follow. Organisations should know what data a system learned from. They should check outcomes for different groups rather than only overall accuracy. And they should keep a human route to challenge a result. The proposal in the Prometheus Endeavour principles that AI-assisted applications be subject to sectoral regulation and external audit points the same way. An outside check is more credible than an internal one on the question of fairness, because the party that built the system has an interest in how it is judged.
Individuals cannot audit a model, but they can ask questions. When an automated tool is used in a decision about you, ask what role it played, whether a person reviewed the outcome and how to dispute it. Those questions match the accountability and transparency qualities that standards bodies describe, and they are reasonable whether or not a specific law applies.
How governments approach generative AI
Governments regulating generative AI are mostly working on a few recurring questions: what data the models are trained on, what suppliers must show before release, which uses are off limits and how outputs are labelled. Generative AI is the branch of artificial intelligence that creates new content such as text, images and music, as the commentary on AI regulation and self-regulation describes it. Its examples include OpenAI’s GPT models, which can understand context and generate human-like text. Because these systems produce content rather than a score, the risks shift from unfair sorting to misleading output, copyright disputes and misuse.
The Prometheus Endeavour principles show how these questions can be turned into duties. They are proposals, not a description of any single country’s law, and each can be read as a different lever.
- Legal training data (Principle P3). Suppliers must be held accountable for ensuring that collection of their training data is legal, which includes respecting copyright and subscription paywalls. This ties generative AI to the creator economy, which AI and Copyright Law: What Creators and Businesses Need to Know in 2026 – Technopolicy examines in detail.
- Self-certification before release (Principle P5). Suppliers certify their own compliance before products reach third parties. This is light-touch and quick, but it relies on the supplier’s own honesty, which is why it is usually paired with audit.
- Forbidden applications (Principle P7). Regulators may define uses that are forbidden, with mass surveillance and toys encouraging dangerous behaviour given as examples. A ban is the bluntest tool and fits cases where no safeguard makes the use acceptable.
- Sector rules and external audit (Principle P8). AI-assisted applications in areas such as health, transport, financial services and education are subject to sectoral regulation and liable to external audit.
These levers differ in cost and strictness. Self-certification is cheapest and suits low-risk uses. Sector rules with audit suit settings where an error injures someone. Bans are reserved for the narrow set of uses judged unacceptable. When you read a new national law, sort its provisions into these buckets and you will quickly see whether it leans on declarations, outside checks or prohibitions.
Where model providers fit
Suppliers of general-purpose models face a distinct set of questions, because one model can be used in many products and sectors. Voluntary codes are one way regulators approach that problem. Providers and their customers who want to see how such a code treats model providers can read gpai code of practice.
Data protection as the older layer
Generative AI does not enter an empty legal field. Existing privacy law already applies to the data these systems use. The GDPR, for example, requires explicit user consent for data collection in Europe, according to the same technology commentary. For readers, the practical point is that a company building or using a model can face obligations from privacy law and from AI-specific rules at the same time. The question is which layer is stricter for the use in question.
Deepfakes and what happens to information
The main risk of deepfakes is that people can be fooled by synthetic voices and fake videos. According to MakeUseOf’s explainer on AI regulation, published on 26 October 2023, individuals not well-versed in AI might easily be fooled by synthesized voices and deepfake videos. The same article notes that criminals can quickly synthesize voices and generate deepfake images. Together these describe two kinds of harm: deception of ordinary viewers and listeners, and fraud by people who exploit that deception.
Why this is an information problem as well as a crime problem
A single convincing fake is harmful to the person deceived. The wider damage is to trust in recordings generally. When synthetic media is easy to produce, genuine material can be doubted, and genuine fakes can circulate before anyone corrects them. That makes disclosure rules important alongside criminal penalties. The proposal in Principle P6 of the Prometheus Endeavour set is a good example. AI search tools should inform the searcher that AI has been used to generate the content. The rule does not stop anyone producing content. It protects the reader’s ability to weigh what they see.
Public understanding is a further factor. MakeUseOf notes that most of the facts end users know about AI come from media outlets. That makes accurate, careful coverage part of the regulatory environment, because it shapes how people judge what they see. Newsrooms face their own questions about how they use AI and how they label it, which ai in journalism ethics explores.
What to check when you meet a suspicious clip or call
- Treat urgency as a warning sign. Fraud depends on speed, and a cloned voice asking for money or secrecy is a reason to pause and verify through a channel you already trust.
- Look for a label. Where disclosure rules exist, AI-generated search content may carry one. Absence of a label is not proof of authenticity, because enforcement and coverage vary.
- Check the law where you live. Rules on deepfakes differ by place, and Which States Make Deepfakes Illegal? The 2026 State-By-State Guide For Consumers And Creators – Technopolicy sets out the position state by state for United States readers.
Work, learning and sector rules
AI rules reach jobs and classrooms mainly through sector regulation. The proposal that AI-assisted applications in health, transport, financial services and education be subject to sectoral rules and external audit recognises that a tool’s risks depend on where it is used. A writing assistant has different stakes from a system that screens job applicants or assesses students. The same reasoning applies to workplaces, even though the proposal does not name them. Software that ranks candidates or monitors staff affects pay, promotion and employment security, so the fairness and accountability expectations covered earlier apply directly.
For employers the sensible approach is to treat any tool that influences a decision about a person as higher stakes than one that only drafts text. Ask what the tool does, what data it learned from and whether a person can overrule it. For workers and applicants, the corresponding step is to ask whether an automated tool is used, and what route exists to have a decision looked at again.
Learning and the long view of work
Education is the other major setting. Tools that support learning can be useful, and the sector-rule proposal means they would be judged by the standards of education rather than general consumer technology. How AI Is Transforming Learning: 7 Key Benefits For Students And Educators In 2026 – Technopolicy sets out the case for the benefits. On how jobs and skills may shift over time, The Future Of Work: How Jobs, Skills, And Places Of Work Will Change By 2030 – Technopolicy gives the broader picture, and The Future Of Work With AI: How Jobs, Skills, And Teams Will Change By 2030 – Technopolicy looks at how teams adapt. Regulation shapes this future indirectly, by deciding which uses need audit, which need disclosure and which are not allowed.
The infrastructure behind AI systems
Every AI system runs on physical hardware, and the rules that apply to a model eventually apply to services run from racks of servers like those in a data centre. Training data duties, self-certification and audit all depend on being able to trace what a supplier built and how it operates. That is easier when the supplier’s computing is documented, which is one reason accountability proposals focus on the supplier rather than only the end product.
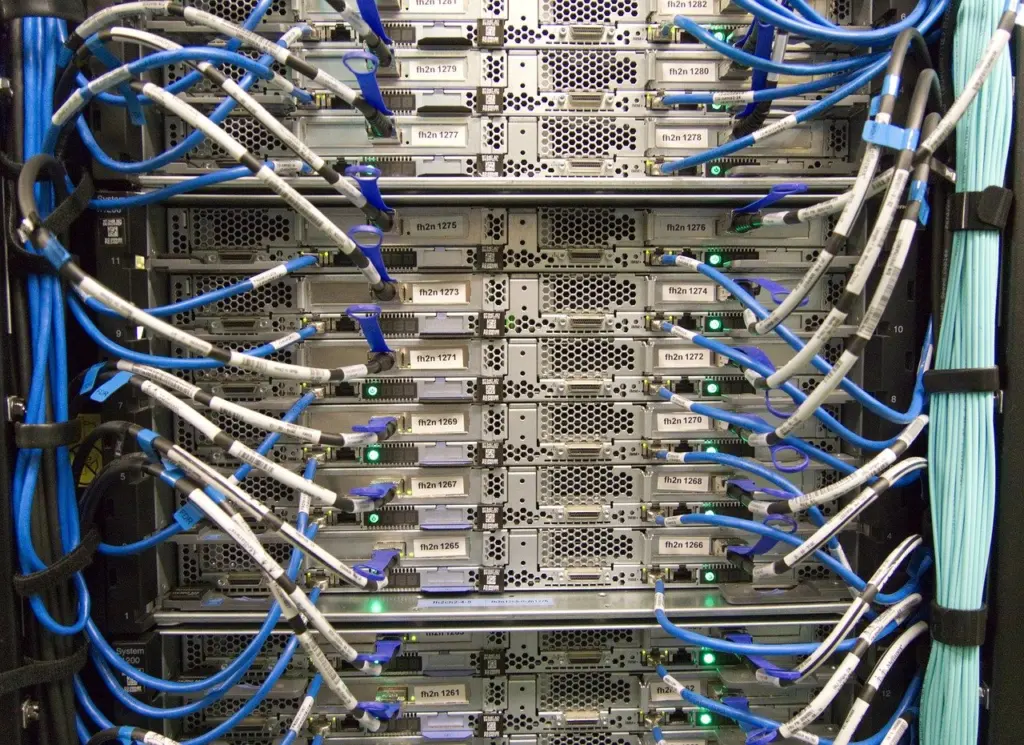
Infrastructure also raises resource questions that sit outside the usual fairness and information debates. The environmental side, including how much water AI systems use, is covered in AI And Water: The Hidden Environmental Cost — How Much Water Does AI Consume In 2026? – Technopolicy. For policy readers, the lesson is that regulation can target outputs, such as labelling, or inputs, such as data and resources. A complete picture needs both.
Standards, certification and reporting
Standards, certification and incident reporting are the practical tools that turn principles into routine practice. Where the law sets a goal such as trustworthy AI, these tools describe how to show you have met it. NIST’s characteristics give a checklist of qualities. Certification can show that a person or organisation has been trained in applying them, and reporting systems give the wider community evidence of what goes wrong.
- Professional certification. For individuals and teams who need recognised skills in responsible AI, AI Ethics Certification: How To Choose, Get Certified, And Stay Current In 2026 – Technopolicy explains how to choose a programme. It suits compliance staff and developers more than casual users.
- Incident learning. A public record of failures lets regulators and developers see patterns. Readers who want to understand what such records reveal can look at the ai incident database guide.
- Protection for insiders. People inside organisations are often the first to see a problem. The ai whistleblower protection act guide explains what such protection covers.
The three are complementary. Certification builds capacity before a problem, incident records record what happened, and whistleblower protection helps problems come out when internal channels fail. An organisation that relies on only one has a gap.
The trade-offs and the disagreement
Regulation has costs, and serious people disagree about them. One recurring concern, reported in MakeUseOf’s explainer, is that government regulation might inadvertently stifle innovation. That is a legitimate worry, and it affects design. Broad, vague rules can burden small developers more than large ones, while narrow rules can miss new uses. The tiered levers described earlier are partly a response: apply self-certification where risk is low, and reserve audit and prohibition for settings where harm is serious.
A different line of argument questions the pace of development itself rather than the details of regulation. Why Some Ethicists Oppose Accelerating AI: 3 Core Arguments and What They Mean (2026) – Technopolicy sets out those positions. Reading both sides helps explain why national approaches differ so much in strictness, even when they use similar language about trust and safety.
The innovation concern and the harm concern are not simply opposed. Clear, predictable rules can help responsible developers by setting a standard that competitors must also meet. The sharpest conflict arises where rules are unclear or enforcement is inconsistent, since the honest actor bears the cost and the careless one does not.
Concerns, proposed responses and how to use them
The table below compares the everyday concerns covered above with the policy response associated with each, so you can see which tool addresses which problem.
| Everyday concern | Policy response | Planning use |
|---|---|---|
| Biased automated decisions | Trustworthy AI defined with fairness and harmful bias managed | Ask whether outcomes are checked across groups, not only overall accuracy. |
| Unlawful training data | Suppliers accountable for legal collection, including copyright and paywalls (P3) | Creators and buyers should ask where a model’s data came from. |
| Unlabelled AI search content | Searchers told AI generated the content (P6) | Treat a label as helpful but not as proof that unlabelled material is human-made. |
| Unacceptable uses | Regulators may forbid applications such as mass surveillance (P7) | Check whether a planned use falls into a prohibited category before building it. |
| High-stakes sectors | Sectoral regulation and external audit for areas such as health and education (P8) | Expect stricter checks the closer a tool is to a decision about a person. |
| Fake voices and videos | Awareness of synthetic voices, deepfake videos and fraud | Verify urgent requests through a channel you already trust. |
The principle labels and the sector, data and search measures come from the Prometheus Endeavour proposals, and the deepfake risks from MakeUseOf’s explainer.
Frequently asked questions
How does AI bias affect people?
AI can perpetuate biases present in its training data, so an automated tool can repeat past unfairness in decisions such as hiring or policing. NIST’s trustworthy AI definition says systems should be fair, with harmful bias managed.
How are governments regulating generative AI?
Approaches centre on a few levers. They cover legal training data, supplier self-certification, forbidden applications, sector rules with external audit and disclosure when AI generates content. Privacy law such as the GDPR also applies where personal data is collected.
What are the risks of deepfakes?
People can be fooled by synthesized voices and deepfake videos, and criminals can quickly create fake voices and images. The result is both individual fraud and weaker trust in genuine recordings.
Is the NIST AI Risk Management Framework a law?
No. NIST is a standards body, and its trustworthy AI characteristics are a reference for good practice. They include being valid, reliable, safe, secure, accountable and transparent. Laws may draw on that vocabulary, but the standard itself does not create legal duties.
Does regulation harm innovation?
It can, if rules are broad or unclear. Government regulation might inadvertently stifle innovation, which is why many proposals apply lighter duties to low-risk uses and stricter ones to high-stakes settings.